Secure Today, Exposed Tomorrow: The Case for Continuous Hardening
About Core6™
StorageGuard - by Core6 - is the ONLY Security Posture Management solution for Storage & Backup systems, helping to ensure these systems are secure and compliant.
Why storage and backup hardening is a process you run, not a project you finish.
If you’ve spent any real time running storage or backup infrastructure, you know the feeling. You finish a hardening effort. You’ve gone through the arrays, closed the gaps the last audit flagged, tightened the backup configs, and documented everything. For a brief, satisfying moment, the environment is clean.
You close the ticket. You move on to the next fire. And somewhere in the back of your mind is a quiet thought: “clean” has a shelf life. It’s shorter than anyone in the audit meeting wants to admit.
That gap is what this post is about – the gap between the environment you signed off on and the environment you actually have three months later. Because the way most organizations still approach storage security was built for a world that no longer exists.
The end of the periodic review
For a long time, the periodic security review made sense. You’d bring in the checklist once a year, maybe once a quarter if you were diligent. You’d walk the environment against a baseline, fix what was broken, and produce a report that said you were in good shape. Everyone signed it. The auditors were happy.
And for the most part, the model held. Not because it was perfect, but because infrastructure changed slowly enough that a snapshot taken in March was still roughly true in September.
That assumption has quietly stopped being true. And if you’re honest about your own environment, you already know why.
Think about how much your storage and backup estate actually changes in a normal quarter. Firmware and software updates land across arrays, appliances, and data protection software. Someone spins up a new volume and sets the permissions “temporarily” — and never revisits them. A replication relationship gets reconfigured during a migration. An admin account gets created for a vendor engagement and outlives it. Retention policies get adjusted. A snapshot schedule gets tweaked to relieve pressure on a busy window.
None of these are mistakes. They’re the normal metabolism of a working infrastructure. But every one of them can move a configuration off its hardened baseline. And none of them wait politely for your next scheduled review.
So the periodic model has a structural flaw that no amount of diligence can fix. It tells you your posture on one day, then asks you to trust it for the next ninety. The review isn’t wrong when you do it. It just starts decaying the moment you finish. And you can’t see that decay until the next review comes around – by which point you’re not looking at your current environment. You’re looking at an archaeological record of the one you used to have.
Hardening is a process, not a project
Here’s the mental shift that actually matters. It’s less about tooling than about how you frame the work.
We tend to talk about hardening as a thing you do – a project with a start, a middle, and a satisfying end. You scope it, resource it, execute, and close it out. That framing is comforting. It’s how we manage most infrastructure work, and it produces a clean deliverable you can point to.
But it misdescribes what hardening actually is. Hardening isn’t a state you reach. It’s a state you maintain, against constant pressure to drift away from it.
The closest analogy isn’t a construction project. It’s the operational discipline you already apply everywhere else. You don’t monitor capacity once a year. You don’t check replication health quarterly and assume it holds. You don’t run a backup, confirm it worked in January, and never look again.
Those things are continuous for a reason. You know from hard experience that the environment doesn’t sit still, and that finding out something broke months later costs far more than watching it all along. Security posture is no different. It drifts exactly the way capacity and replication health drift – silently, incrementally, through a thousand small legitimate changes. It deserves the same continuous attention, not a once-a-year physical.
Reframing hardening this way changes what “done” means. Under the project model, done means the report is signed. Under the process model, there is no done. There’s only one question: how quickly do you notice when something moves off baseline, and how fast do you bring it back?
That sounds like more work. In a manual world, it would be. But it’s actually the opposite. Continuous hardening replaces the huge, disruptive, all-hands effort of a periodic review-and-remediate cycle with a steady, low-drama process of catching small drifts before they compound. The annual audit stops being a scramble — because the environment was never allowed to drift far in the first place.
Why this matters more than it used to: how attackers exploit infrastructure weaknesses
You could reasonably ask: infrastructure has always drifted, so why is continuous hardening suddenly urgent rather than just good hygiene? The answer is speed. The people looking for these weaknesses have gotten dramatically faster and less selective. That changes the math on how long you can afford to leave a gap open.
Start with how your infrastructure looks from an attacker’s perspective, because it’s not how we tend to think about it internally. We see arrays, appliances, and management consoles — the tools of the job. An attacker sees something else: management interfaces, service accounts, default credentials that were never changed, exposed protocols, and configuration weaknesses. Each one is a potential way in.
And they’re specifically interested in this layer for a simple, uncomfortable reason. It’s where the data lives. More importantly, it’s where the ability to recover data lives. Compromising a backup environment isn’t a side objective anymore. For anyone running a ransomware operation, neutralizing recovery is the whole game. Corrupt or delete the backups, disable immutability, or quietly alter retention before touching production, and a recoverable incident becomes an existential one.
What’s changed recently is how fast this happens. Finding an exploitable weakness in a specific storage or backup platform used to take real, scarce expertise – reading the advisory, understanding an unfamiliar system, working out which configurations are actually exposed, and building something to take advantage of it. That scarcity was a kind of protection. Attackers rationed their effort and left a lot of infrastructure alone simply because it wasn’t worth the hours.
AI is dismantling that protection. The tasks that used to gate an attack are exactly the ones these tools accelerate. The window between “a weakness in your platform becomes known” and “someone is actively trying it against you” has collapsed from months toward days. And because the effort is lower, attackers are far less selective. The overlooked backup appliance in a branch site is no longer beneath notice.
Put the two halves together and the risk is clear. Your environment drifts continuously through normal operations. The time between a weakness appearing and someone exploiting it has shrunk dramatically. A periodic review can’t close that gap, because it isn’t looking most of the time – and “most of the time” is now exactly the interval an attacker needs. The exposure isn’t just that weaknesses exist. It’s how long they sit there undetected between reviews. Duration is the variable, and the periodic model maximizes it by design.
What continuous hardening looks like in practice
Moving from periodic to continuous doesn’t mean auditing yourself to death or drowning your team in manual checks. That would be unsustainable, and it’s the opposite of the point. It means the environment is assessed continuously rather than occasionally.
In practice, that’s three things. Configurations across your multi-vendor estate get checked against known-good baselines and vendor best practices on an ongoing basis. Drift is surfaced as it happens, not discovered months later. And the weaknesses that actually matter are prioritized — so your team spends its limited time on what’s most likely to be exploited, not on working through an undifferentiated list.
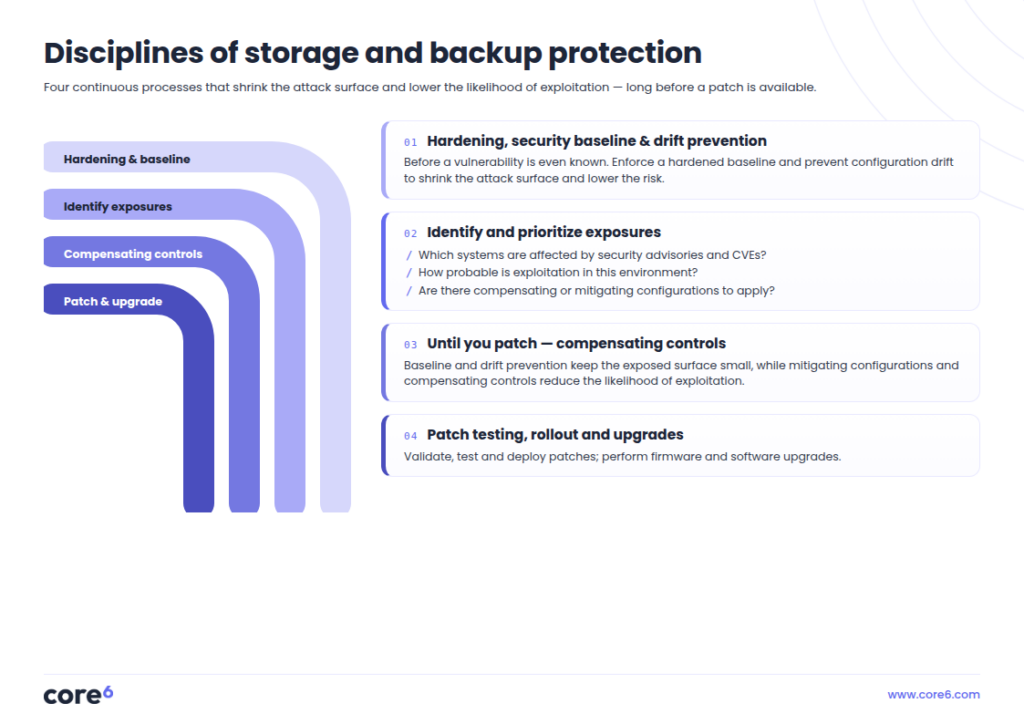
This is the problem StorageGuard was built to solve. Rather than treating hardening as a periodic project, it continuously assesses configurations across enterprise storage, backup, and recovery systems from multiple vendors. It checks them against vendor hardening guidelines and established baselines like NIST and CIS, and flags drift and exposures as they emerge.
The gap between something moving off baseline and your team knowing about it stays measured in a timeframe you can actually act on. It’s built to fit the way infrastructure teams already work – continuous, prioritized, and focused on keeping the environment hardened rather than proving it was hardened once.
The shift here isn’t really about buying a tool. It’s about retiring an assumption. The assumption that a point-in-time review reflects your live environment stopped being safe some time ago. The change in attacker speed has just made the cost of clinging to it a lot higher.
Storage and backup infrastructure doesn’t hold still. The security posture of something that doesn’t hold still can’t be managed as though it does. Treat hardening as the continuous process it actually is, and “secure today, exposed tomorrow” stops being the quiet fear at the back of your mind. You’ll know about tomorrow’s exposure tomorrow – not at next year’s audit.
Want to know where you actually stand?
Reading through five domains is one thing; knowing how your own estate scores against them is another. That’s exactly why we built the Enterprise Storage & Backup Security Self-Assessment.
It walks you through these same five domains and gives you back a weighted scorecard that surfaces your gaps and shows you which controls to fix first.
Take the Enterprise Storage & Backup Security Self-Assessment
Frequently Asked Questions (FAQs)
What is continuous hardening for storage and backup infrastructure?
Continuous hardening is the practice of assessing storage and backup configurations against secure baselines on an ongoing basis, rather than through periodic reviews or annual audits. Because infrastructure changes constantly — firmware updates, new volumes, permission changes, reconfigured replication, adjusted retention policies — a configuration that was hardened at the last review can quietly drift out of a secure state. Continuous hardening detects that drift as it happens, validates configurations against vendor best practices and standards like NIST and CIS, and surfaces weaknesses so they can be remediated before they are exploited. It treats hardening as an ongoing operational process rather than a one-time project.
Why are periodic storage security reviews no longer enough?
Periodic reviews capture an environment’s security posture at a single point in time, but storage and backup infrastructure changes continuously through normal operations. Between reviews, configurations drift as teams apply updates, provision new storage, adjust policies, and make routine operational changes — none of which wait for the next scheduled audit. This means a review is only accurate on the day it’s performed and steadily decays afterward, leaving the organization blind to new exposures until the next review months later. Because AI has dramatically shortened the time between a weakness becoming known and being exploited, those blind intervals now represent real, exploitable risk.
Why is hardening a process rather than a project?
Hardening is a process because a secure configuration is not a permanent state you reach and keep — it’s a state you have to maintain against constant pressure to drift away from it. Every legitimate operational change, from a firmware update to a new admin account, can move a system off its hardened baseline. Framing hardening as a project with a start and an end creates a false sense of completion, because the environment begins drifting the moment the project closes. Treating it as a continuous process — like capacity monitoring or backup verification, which teams already run continuously — keeps the environment close to baseline at all times and turns the annual audit into a formality rather than a scramble.
How do attackers exploit storage and backup infrastructure weaknesses?
Attackers target storage and backup infrastructure through exposed management interfaces, unchanged default credentials, unnecessary service accounts, open protocols, and configuration weaknesses that accumulate as environments drift. They focus on this layer because it holds both the data and the ability to recover it. In ransomware operations, compromising the backup environment is a primary objective: by corrupting or deleting backups, disabling immutability, or altering retention before attacking production, attackers remove the victim’s ability to recover without paying. AI has accelerated this by making it faster and cheaper to identify and exploit platform-specific weaknesses, shortening the time between a vulnerability becoming known and being actively targeted.
How does StorageGuard support continuous hardening?
StorageGuard continuously assesses configurations across enterprise storage, backup, and recovery systems from multiple vendors, checking them against vendor hardening guidelines and established baselines such as NIST and CIS. Instead of relying on periodic reviews, it detects configuration drift and security exposures as they emerge, and prioritizes the weaknesses most likely to be exploited so infrastructure teams can focus their remediation effort where it matters most. This keeps the gap between a system drifting off baseline and the team becoming aware of it short, allowing organizations to maintain a hardened posture continuously rather than proving it was hardened at a single point in time.
Talk To An Expert
Ensure your storage & backup systems are hardened and compliant.